The market is the first reviewer
The offer leaves the team thinking it's clear, and the first person to point out the gap is whoever already saw the paid ad.
A simulated audience based on your brand responds to the offer, price, and ad before the money leaves. It is not an opinion survey or a real customer: it is a way to hear where your material does not explain itself.
"Pro Plan for R$ 399/month: 25,000 credits and all modules."
Twenty-five thousand credits tells me nothing. How many analyses per month does that cover? I need the numbers before taking this to my boss.
I understand the price, but not what I do on day one. If I subscribe today, what appears on my screen tomorrow?
Does all modules include LogicaOS? The page says "all", the table says it does not. I will assume it does not and distrust the rest.
Example of a trial. The seal next to each profile says what it is: ○ hypothesis approved by you, ◐ derived from data from your operation, ● backed by a conversation that existed. None of them is a real customer, and the platform never pretends it is.
Whoever wrote the offer understands the offer. The trial exists to bring the misunderstanding back: the angle of someone who doesn't know, doesn't trust, or is in a hurry, and it's always one of these three that makes the customer close the tab.
The offer leaves the team thinking it's clear, and the first person to point out the gap is whoever already saw the paid ad.
Interviewing ten customers takes weeks and costs money. For a Tuesday decision, nobody does it, and the call gets made on a guess.
Whoever is in the room shares the same context. The team's blind spot is, by definition, invisible to the team.
The trial doesn't return a score from zero to ten: it returns the objections, in the language of whoever objects, with the piece of material that generated each one. It's material to rewrite, not to frame.
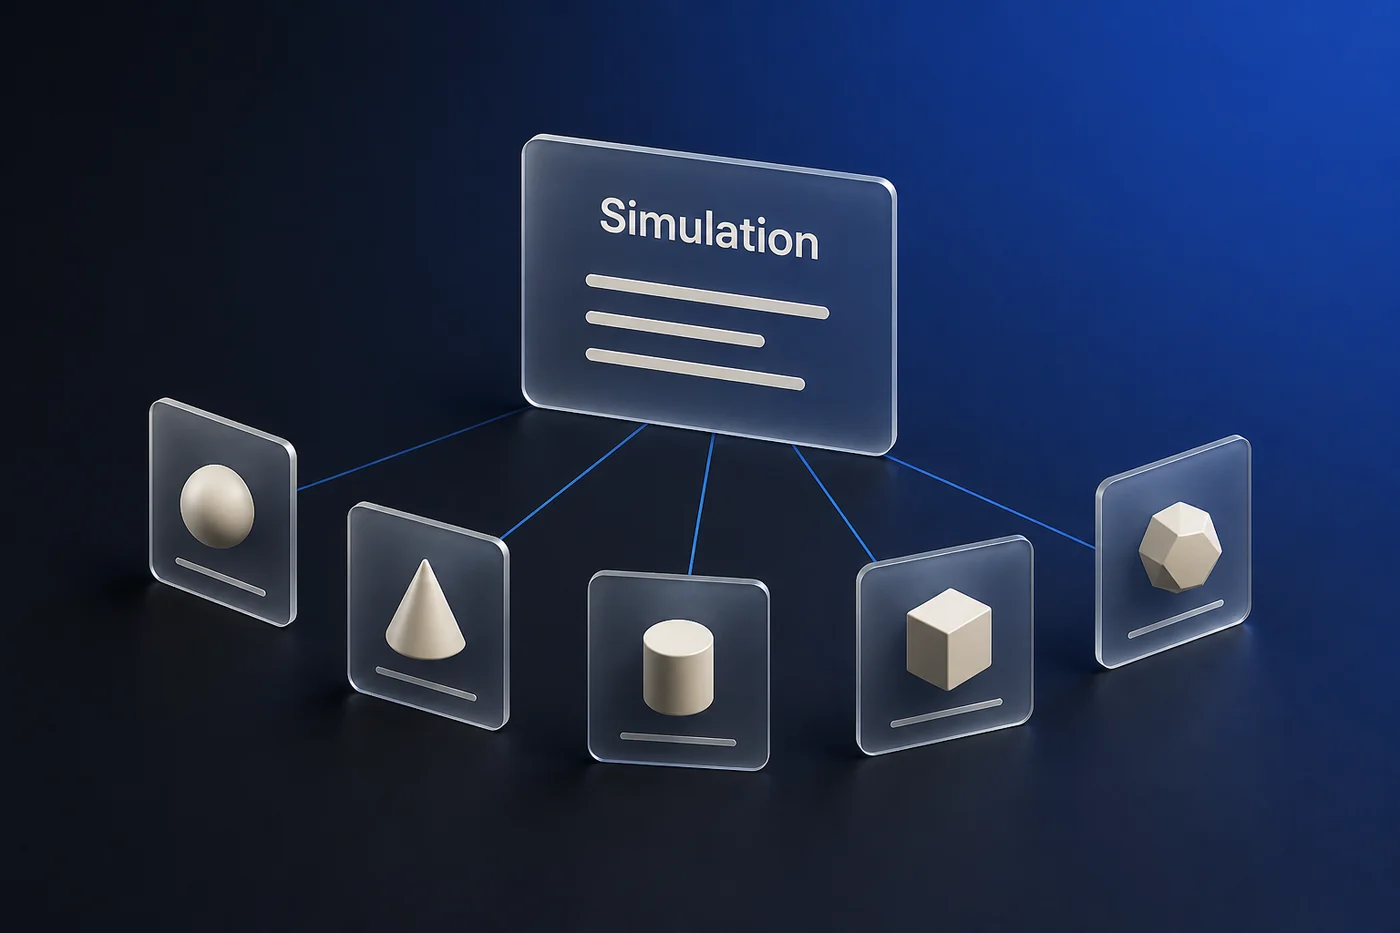
How many different reasons for refusal came up. Two people stalling for the same reason count once: what matters is the variety of the problem.
When different profiles stall on the same point, the problem is with the material. When only one stalls, it's usually the profile.
You approve which ones go in and with what seal. A profile without backing stays marked as a hypothesis until there's data to support it.
Minutes, not weeks. That's what lets you trial before each campaign instead of once a quarter.
Audience simulation is territory where it's easy to sell illusion. We prefer to spell out exactly what this is, because that's the only way the result can be useful.
It's an angle of questioning: a way of looking at your material and not understanding it. That's what it produces of value, and that's the only thing the platform claims.
The platform reads what the company has already published and proposes the profiles. You review and approve, and approving here means "it's plausible for my business," never "it's real."
○ hypothesis, ◐ derived from data from your operation, ● backed by a message that really existed. The seal appears next to every response.
The trial responds based on what your company has published and what Collection brought in from the market. Not generic impressions about your industry.
Research with real people is irreplaceable, A/B testing works, and the team meeting has value. The point is what fits before the decision, and how much it costs to get it wrong.
Based on what your company has already published and your sector. You read, cut what makes no sense and approve the rest as a hypothesis.
The offer, the price, the ad copy or the entire page: whatever is about to go live.
Each one with the profile badge and the excerpt that caused it. What appears in more than one profile is what you rewrite first.
Rewrites the asset before publishing, with the real objection in front instead of a meeting guess.
Gets the most common sticking points already mapped, and the ready answer for each one.
Finds where the proposition is misread, which is almost always a product problem disguised as copy.
Ordered by how many profiles got stuck at the same point.
Which part of your material generated each objection.
The questions your material should answer and does not.
The test result reaches the channel where the asset is being discussed, before anyone hits publish.
The unit is one profile's response to your material. A test run with five profiles costs 15 interaction credits plus 15 for the verdict, and the same balance works across the other modules.
The free plan does not include Oracle. It starts with Hobby, with one thousand interactions per month: enough to test every asset before publishing, with room left over.
See all plansNo, and we do not sell it that way. Research with people returns the truth, with nuance, and is irreplaceable for major decisions. The test run returns objection hypotheses in minutes, which is what fits before an asset goes live on a Tuesday. They are different things, and using one in place of the other goes wrong both ways.
From your brand: the platform reads what the company has published and the sector, then proposes them. You review, cut and approve, and the button says "approve as a working hypothesis" on purpose. Each profile carries a badge showing whether it is a hypothesis, derived from data from your operation or grounded in a real conversation.
That is the central risk of this type of tool, which is why profiles are built as angles of NOT understanding: the person who approves the spend, the person in a hurry, the person who will implement it. A test run is good when it finds a sticking point, not when it praises. If it only praises, either the material is genuinely good or the profiles are poorly calibrated. In both cases, you see the badge and know the weight of what you read.
You can, and that is where the ◐ and ● badges appear: profiles derived from your service history carry more weight than hypotheses. What the platform does not do is pretend a profile has grounding when it does not.
They are, and that is what lets you compare the August and September versions of the same offer. Like everything else, they are yours, encrypted with your key and exportable.
A test run alone is manufactured opinion. Connected to the rest, it responds based on what the company actually published and what the market actually says.
Each one solves a front, and all write to the same memory. See the others and how they fit with this one.