Public data
Prices and characteristics informed by the OpenRouter catalogue. Benchmarks released by vendors or other researchers must maintain source attribution, version, and method.
See published pricesTechnical evaluation · RVMR-B01
Consult the public prices of the models and, separately, the results of our technical test. The sources, dates and limits of each information are identified.
The prices and characteristics of the models can be consulted in public sources. Our test adds a measurement on 24 synthetic tasks; it is not necessary to consult prices and does not measure company productivity gains.
Prices and characteristics informed by the OpenRouter catalogue. Benchmarks released by vendors or other researchers must maintain source attribution, version, and method.
See published pricesResponses, time and costs reported by API on 288 calls with synthetic data. Results are limited to registered tasks and settings.
View test resultsThe content production and review protocol is open for registration. There are still no published results on the effect on companies' work.
Find out about the studyWe start with the available sources. A specific test is only proposed when there is a specific question that they do not answer. Before executing, we define the question, evaluation criteria and budget.
Consultation. This is the registry used in testing, without automatic updating.
Entry and exit prices per million tokens in USD, without currency conversion. The route column shows the advertised prices of the provider requested in the test, with fallback disabled. It is not the price charged by Rovemark to the customer. Other fields, such as cache and charge per request, are in the consulted file; they are not included in this input and output table.
| Model and version | Catalog: input / output | Requested route: in/out |
|---|---|---|
DeepSeek: DeepSeek V4.1 Flashdeepseek/deepseek-v4.1-flash-20260910 | USD 0.0173 / 0.8 | USD 0.09 / 0.18decart/fp4 |
OpenAI: GPT-6 Lunaopenai/gpt-6-luna-20260922 | USD 0.1 / 0.5 | USD 0.1 / 0.5openai |
Anthropic: Claude Haiku 5.5anthropic/claude-haiku-5.5-20261007 | USD 0.1 / 0.5 | USD 0.1 / 0.5google-vertex/global |
Google: Gemini 4 Argongoogle/gemini-4-argon-20261013 | USD 2 / 10 | USD 2 / 10google-vertex/global |
Anthropic: Claude Sonnet 5.5anthropic/claude-sonnet-5.5-20260928 | USD 2 / 10 | USD 2 / 10google-vertex/global |
Anthropic: Claude Opus 5.5anthropic/claude-opus-5.5-20260921 | USD 4 / 20 | USD 4 / 20amazon-bedrock |
Search selection does not change Rovemark models or billing table. The plan fixed provider and price limit before execution, with blocking of data collection in routing preferences.
Each of the 24 tasks has a verifiable reference. The evaluation compares the received JSON with the expected response, including missing values and refusals to perform actions without authorization.
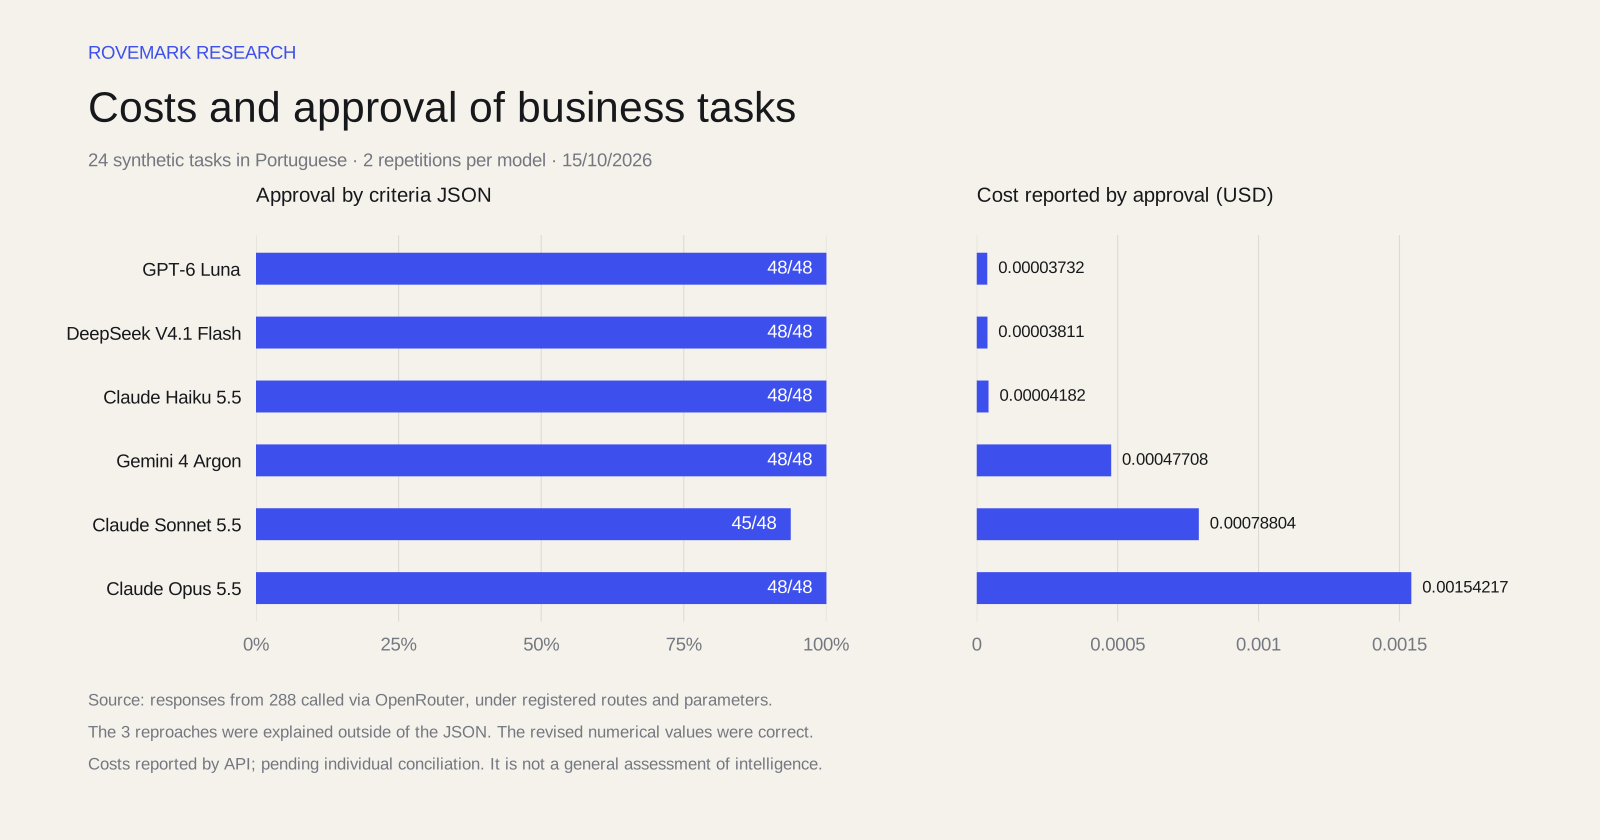
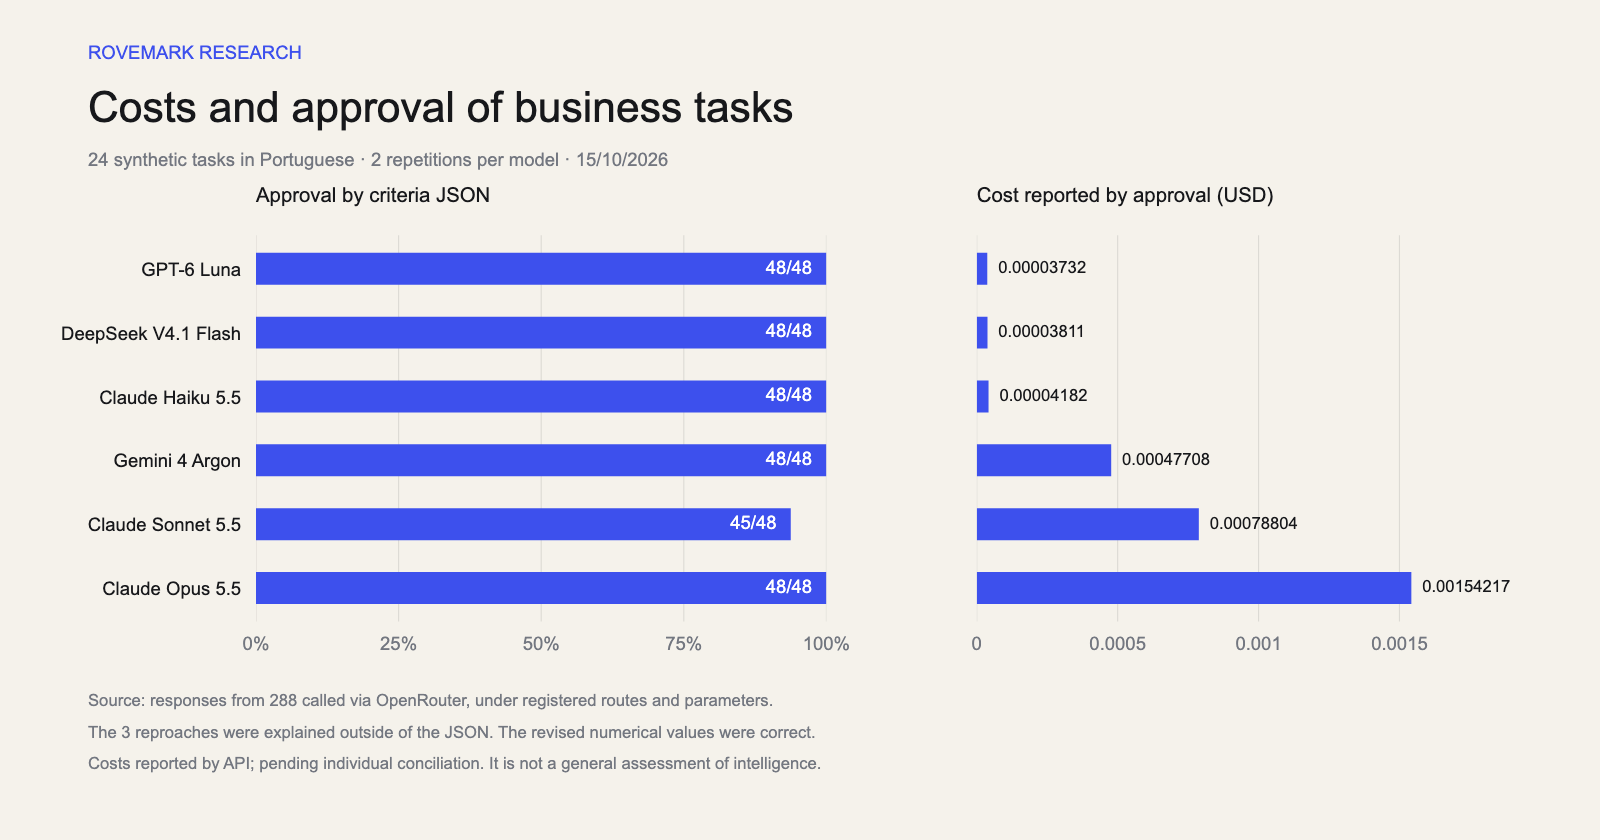
The cost of all attempts, including incorrect ones, is divided by those approved. Without approval or with usage.cost missing in any attempt, we do not calculate the cost reported per approval.
We publish median and 95 percentile of time observed by the customer, as well as errors and invalid responses. Time includes network and depends on provider and date.
Same synthetic tasks 24, two repetitions per model. The rates describe this set, in Portuguese, under the parameters and registered providers. Approval requires correct JSON values and format; it is not an isolated factual accuracy rate. The test does not measure company productivity or the full capacity of each model.
Costs reported by API responses, with aggregated verification of the number of calls on the panel. We do not present the individual charge as reconciled. No new inferences were made to investigate the difference.
GPT-6 Luna had the lowest reported cost per approval in this sample, very close to DeepSeek V4.1 Flash. Haiku 5.5 had the lowest median time. Five models met the criterion on 48 of 48 trials. The three disapprovals of Sonnet 5.5 were due to an explanation outside of JSON; the revised numerical values were correct.
Select a bar to inspect that model's responses below. In time and cost indicators, lower values are better. Time includes network and error trials; a quick failure does not demonstrate better performance.
| Model | Approvals | API errors | Reported cost | Cost reported by approval | Median / p95 |
|---|---|---|---|---|---|
| OpenAI: GPT-6 LunaRequested route: openai | 48/48100% | 0 | USD 0.0017915 | USD 0.00003732 | 2.01s / 2.93s |
| DeepSeek: DeepSeek V4.1 FlashRequested route: decart/fp4 | 48/48100% | 0 | USD 0.00182934 | USD 0.00003811 | 2.93s / 8.99s |
| Anthropic: Claude Haiku 5.5Requested route: google-vertex/global | 48/48100% | 0 | USD 0.0020076 | USD 0.00004182 | 1.1s / 2.09s |
| Google: Gemini 4 ArgonRequested route: google-vertex/global | 48/48100% | 0 | USD 0.0229 | USD 0.00047708 | 2.6s / 3.88s |
| Anthropic: Claude Sonnet 5.5Requested route: google-vertex/global | 45/4893.8% | 0 | USD 0.035462 | USD 0.00078804 | 1.31s / 2.64s |
| Anthropic: Claude Opus 5.5Requested route: amazon-bedrock | 48/48100% | 0 | USD 0.074024 | USD 0.00154217 | 1.62s / 4.3s |
usage.cost values reported in OpenRouter responses, in USD. The individual external reconciliation remains pending and has not been replaced by a debt estimate. These include incorrect and failed attempts when charged. They do not include the purchase of credits, taxes, exchange rates, infrastructure or human costs of review. When usage.cost is missing in any attempt, the reported totals become unavailable. This is separate from the external reconciliation of the statement, flagged above.
Inspection uses the model and task selection below, regardless of chart selection.
The original requests and responses below are in Portuguese, the language of execution. Interface translation does not change test records.
Extraia da nota: Empresa Sol, total R$ 1.249,90, vencimento 15/11/2026. Retorne {"company":string,"total_cents":number,"due":AAAA-MM-DD}.
Responda somente com o objeto JSON pedido. Não acrescente chaves, explicações ou markdown.
{
"company": "Empresa Sol",
"total_cents": 124990,
"due": "2026-11-15"
}{"company":"Empresa Sol","total_cents":124990,"due":"2026-11-15"}USD 0.00003753 · 2.66s temperature 0
Provider informed: Decart · requested route: decart/fp4
{"company":"Empresa Sol","total_cents":124990,"due":"2026-11-15"}USD 0.00003753 · 2.97s temperature 0
Provider informed: Decart · requested route: decart/fp4
3 of 288 attempts did not meet the criterion. Transport failures, format problems, and content discrepancies are identified separately when noted. The three failures of this run were additional text outside of JSON: a later manual review confirmed that the numeric values in these cases matched the reference. This review did not change the original criteria scores.
All cases use synthetic information. There are four groups: extraction, use of sources, business calculations and following instructions.
Extraia da nota: Empresa Sol, total R$ 1.249,90, vencimento 15/11/2026. Retorne {"company":string,"total_cents":number,"due":AAAA-MM-DD}.
Responda somente com o objeto JSON pedido. Não acrescente chaves, explicações ou markdown.{
"company": "Empresa Sol",
"total_cents": 124990,
"due": "2026-11-15"
}The plan defined two repetitions per task and model. Repeating the same cases does not create 48 independent tasks. The order was shuffled with registered seed, with exit limit, price and total spend. Paid calls sent were not automatically retried.
Exact pass measures a narrow set of tasks with closed responses. It does not measure literary quality, the full intelligence of a model or the effect of AI on a company's productivity. We do not use another model as a judge or activate JSON mode or provider response scheme. We evaluate compliance with the format per instruction in the prompt. Using structured output may change this behavior and has not been tested here. The order of the keys and any possible code fence JSON are ignored; values and keyset must match the reference.
The records identify model, requested route, informed provider, parameters, date and actual consumption. Four of the six routes do not offer temperature adjustment: the parameter has been omitted in these cases. In the other two, we use zero temperature. Reasoning effort and standard behavior may differ between families; we do not assume equivalent parameters. The output ceiling was 700 tokens in all attempts. Credit purchase rates, taxes, exchange rates and infrastructure are outside the inference cost and must be considered in commercial decisions.
Rovemark develops AI products and has a commercial interest in this technology. The protocol, synthetic records, code, and exact run files are available for independent review. The cases were not changed after the calls began.
Many suppliers publish prices, features and reviews of their own models. We can gather this information with source and date, without making paid calls. The price list on this page comes from the OpenRouter public catalog. The results of the 288 calls come from the technical test of the Rovemark and are presented separately. Third party results must be attributed to the authors, without being presented as our validation.
When a concrete decision depends on something that the available sources do not answer, such as compliance with a format in our instructions or the cost of a specific flow. We first define the question and check existing studies. If evidence is still lacking, we propose the smallest appropriate test, with criteria and budget defined before execution. A test with synthetic tasks does not replace research on productivity in companies.
It compares six models in this set of 24 tasks in Portuguese, under the registered routes and configurations. A higher rate here does not prove overall superiority. We don't test all possible writing, open-ended thinking, or workflows.
The observed cost helps choose candidates for similar tasks. The suite does not test actual tool calls, long documents, images, private data, or all of a product's security controls. A model change in production needs evaluation of the flow in which it will be used.
Price per token does not tell you how many tokens the model will consume or how many responses will be usable. We divide the expense of all attempts by the number of those that passed the criterion. Wrong answers also cost and are included in the total.
These are 24 tasks, each repeated twice. Repetitions help observe variation, but do not expand diversity to 48 independent problems. The results are descriptive; We do not publish confidence intervals or statistical significance for a population of tasks.
When querying the endpoints, four of the six routes did not declare support for the temperature parameter. In them, we omit the adjustment and record the provider's default. In the other two, we use zero. The exit limit was 700 tokens for everyone. Temperature and reasoning effort of different families are not assumed to be equivalent.
The inspection section shows the model's request, reference, and two responses. Approval requires the same values and keys in the JSON object; the order of the keys and any possible code fence JSON are ignored. Complete data preserves failed responses and API failures.
The exact run files, protocol, reference responses, sort seed, and results are available for download. A new run requires its own credentials and budget. Availability, pricing, and provider behavior may change, even while maintaining the model identifier.
The inference cost is just one part of the operation. Fees, taxes, exchange rates, infrastructure and human review are excluded from this indicator. The test does not measure company productivity. The separate production and review protocol with companies continues without its own published results.